Enterprise Code Search Tools Ranked by Monorepo Indexing Performance
Lexical filtering plus semantic ranking beats pure approaches for monorepo search.
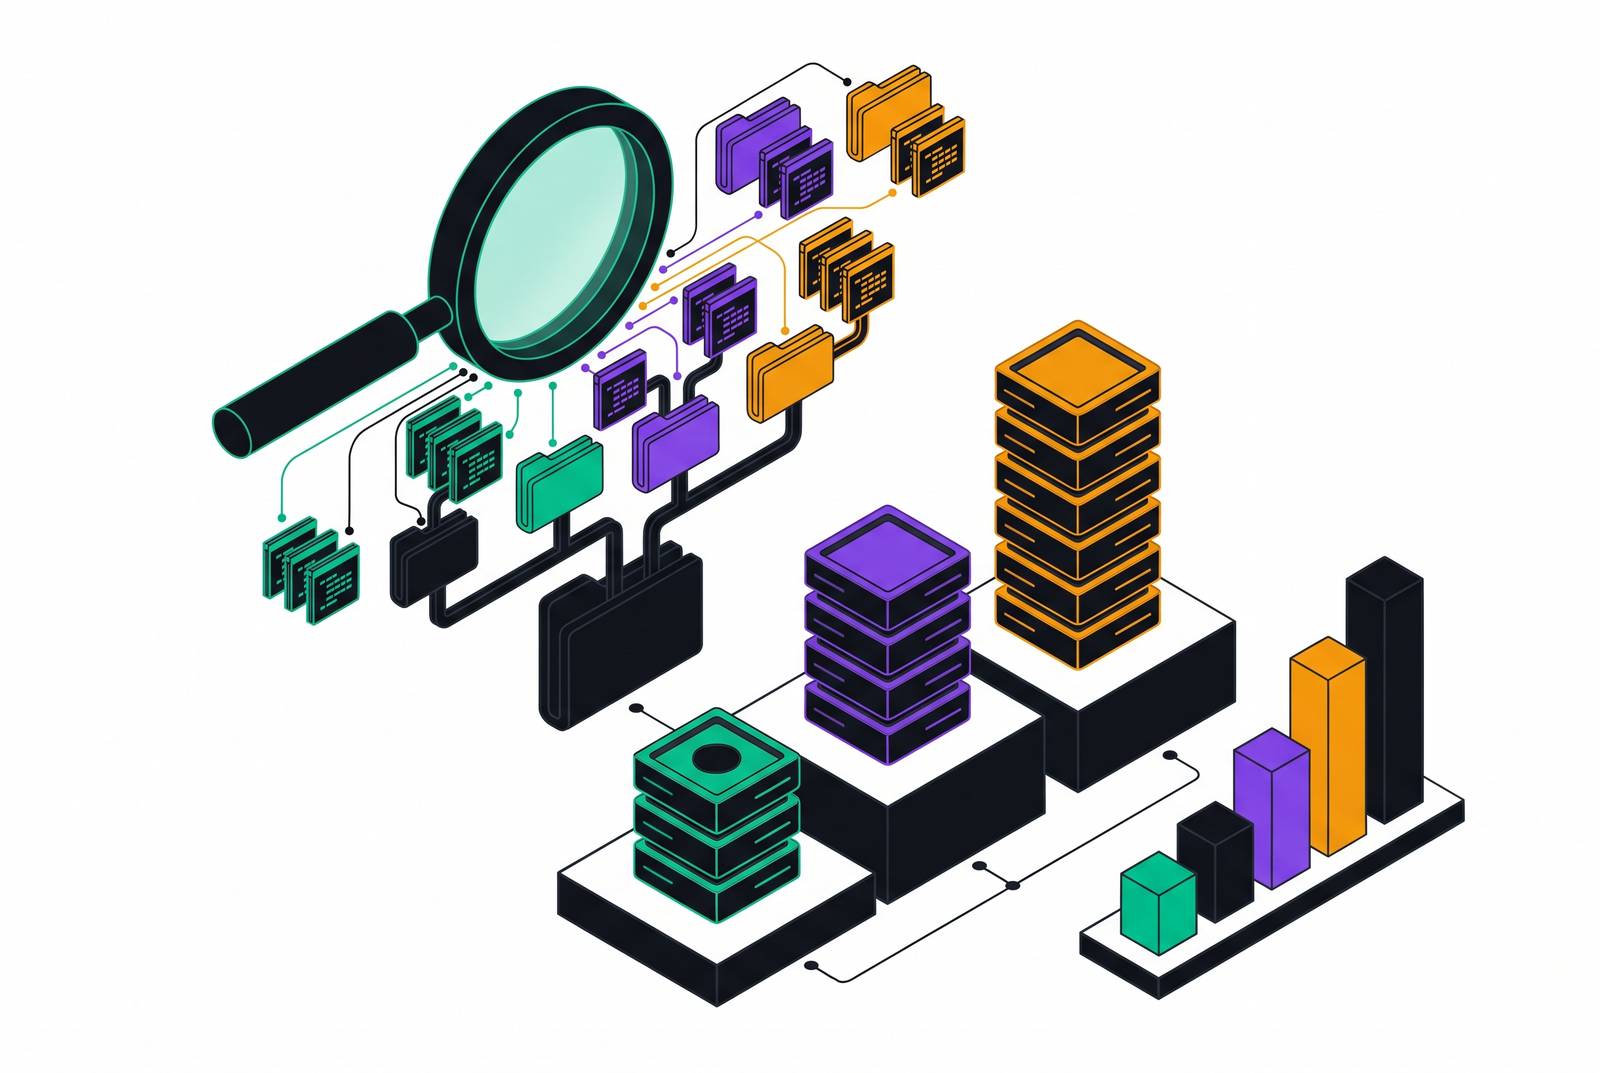
Enterprise code search retrieves text, symbols, and behavior across large codebases. For monorepos, the strongest architecture combines lexical filtering with semantic ranking. GitHub Code Search and Zoekt suit literal search, OpenGrok and Meta’s Glean emphasize structure, and CocoIndex provides a semantic indexing component. The best choice depends on query type, how fresh the index is, and where the tool can run, so a universal benchmark ranking cannot decide it.
Why indexing architecture determines monorepo search performance before any feature comparison begins
Benchmark rankings circulate, vendors claim the top slot, and teams still choose tools that do not fit their codebase. The mismatch starts beneath the feature checklist. Monorepos concentrate code, contributors, and cross-cutting dependencies into one index target, exposing differences that smaller repositories hide. A result from a small codebase that rarely changes therefore says little about how well search works across millions of files that change often.
Regex support, language filters, SSO, and MCP connectors remain real requirements, but their usefulness depends on the engine beneath them. An engine must make the whole codebase searchable without making developers wait while it checks files that do not matter to the query. Different architectures divide that work differently, so a useful comparison begins with how each engine eliminates candidates, recognizes structure, and ranks results.
How lexical indexing works and where its performance ceiling sits
Lexical indexing maps raw text to file locations. A trigram index records every three-character sequence and uses the intersections of posting lists to find files that could match a string query. This saves it from checking every file for every search. It supports fast substring and regex retrieval without understanding what the code does, making it a strong baseline for known identifiers, configuration keys, and error strings.
GitHub’s engineering documentation describes Blackbird, its custom Rust engine, as constructing distinct n-gram indexes for content, symbols, and paths, with metadata supporting scoped retrieval. Google’s internal code search used trigram-based search over roughly 1.5 TB of code, with median latency in the tens of milliseconds. Its index later evolved through a custom suffix-array approach to sparse n-grams for regex search. These are engineered indexes.
Zoekt makes the performance profile concrete at a more accessible scale. It indexes tens of thousands of files in seconds at kubernetes/kubernetes scale, with sub-second filtered queries. That does not establish constant-time behavior as repositories grow, because posting-list size still affects the work. Its harder limit is expressiveness. A query for OAuth token validation can find the code only if the query’s words match searchable text, even when the intent describes what the code does.
What AST-based and symbol indexing add on top of lexical search
An abstract syntax tree, or AST, gives an index access to code structure. Indexing definitions, references, call sites, and inheritance enables questions about where a function is defined, what calls a method, or which classes implement an interface. These retrieval tasks go beyond what better string matching can do. Meta’s Glean stores such relationships as structured facts in a queryable database, supporting structural questions across repositories.
Some symbol indexes cover only part of that relationship model. GitHub Docs specify that Blackbird’s symbol qualifier finds definitions only, while its symbol index uses the same n-gram family as its content and path indexes. Scope therefore needs careful inspection in any comparison. Structural retrieval can be precise without answering where payment retries are handled when names do not encode that intent. Language-specific analyzers also create potential coverage gaps in polyglot monorepos, even when supported languages receive deep analysis.
Why semantic-only indexing fails as a primary index at monorepo scale despite its recall advantage
Semantic indexing represents code chunks as dense vectors and retrieves them by similarity. This improves recall when a developer describes behavior. The gain is real and useful. For an agent seeking the implementation relevant to a task, finding the right code can outweigh the speed of returning a literal but unhelpful match.
A semantic-only design that embeds or compares the full corpus on the query path has no lexical pre-filter to discard irrelevant files first. Its latency burden grows with the corpus. That failure mode belongs to the full-corpus query design. Precomputed embeddings move generation out of the request path, but leave ingestion cost and freshness to manage.
For a large monorepo, full embedding on a single high-end GPU node can take multiple hours. Running embedding jobs on commits adds work to CI and creates lag between changed code and searchable semantic state. Frequent commits amplify that operational burden. The architecture can retain semantic retrieval by placing expensive semantic judgment behind a selective retrieval stage and amortizing embedding generation where possible.
How the hybrid architecture resolves the latency-recall tradeoff that pure approaches cannot
A hybrid architecture assigns elimination to the lexical tier and judgment to the semantic tier. Its three-tier design makes that division explicit. Tier 1 is the lexical pre-filter, where a trigram index reduces millions of files to a small candidate set in milliseconds. In practice, selective queries can grow much more slowly than a full scan as the repository expands, though the index does not provide an unconditional constant-time guarantee.
Tier 2 is the semantic embedding store, using a pre-trained code embedding model such as CodeBERTa to provide dense representations for the filtered candidates. Tier 3 is the cross-encoder reranker, which combines lexical and semantic signals into the final ranking. The expensive query-time model sees only the candidates. Where embeddings are precomputed, their generation belongs to ingestion.
Pre-filter selectivity is the decisive variable. A small candidate set leaves more of the latency budget for semantic judgment. But a reranker cannot bring back relevant code dropped before it runs, so teams must check candidate coverage along with response time.
Ingestion and querying therefore have different cost profiles. Teams can accept an amortized embedding cost when the query-time gain justifies it, but that cost introduces another failure mode. A silently failed embedding job can leave latency looking normal while semantic recall deteriorates. Monitoring embedding freshness is consequently a required part of operating the architecture.
What is the best enterprise code search tool for large monorepos in 2026?
GitHub Code Search is a strong fit when the priority is hosted literal search across GitHub repositories. Blackbird’s multi-faceted n-gram architecture supports regex, boolean operators, and scoped symbol definitions. It has no native semantic tier for intent-based questions. Because it is cloud-hosted, it also cannot meet a requirement to keep all code inside the customer’s environment.
Zoekt is the principal open-source option for teams seeking a controllable trigram search core. Its demonstrated filtered-query performance makes it a useful lexical backend. Platform teams build the surrounding system. It can index repositories and branches across GitHub, GitLab, and other hosts, and teams can compose a semantic reranker around it.
OpenGrok fits a different workload, emphasizing source browsing and cross-references for large, long-lived Java and C codebases. It has two decades of operational history. The project, which Oracle owns and the community maintains, uses CDDL 1.0 and lists release 1.14.20 dated October 12, 2026. Its self-hosted structural navigation is useful on-premises, but it does not offer intent-based semantic search.
Glean goes deeper into queryable code relationships, storing definitions, references, inheritance, and call chains as facts. Meta’s engineering documentation describes a general-purpose system supporting IDE features, search, documentation, and code review. Significant infrastructure and engineering investment are required. The same documentation describes incremental indexing, including C++ dependency fanout, so daily full rebuilds should not be treated as an inherent requirement.
CocoIndex addresses the semantic ingestion side. Its Rust engine, Python pipeline definition, and native Tree-sitter parsing support syntax-aware chunking and incremental re-embedding. CocoIndex’s documentation describes live-mode updates that reprocess only changed chunks on file save. Teams supply the embedding model and vector database, with Postgres and pgvector used in the documented setup, then compose a query layer around the self-hosted pipeline.
GitHub and Zoekt compete most directly on literal retrieval, OpenGrok and Glean serve structural workloads, and CocoIndex supplies a component for semantic indexing. None of those descriptions alone establishes a measured winner for the complete three-tier pipeline. A hybrid evaluation must inspect the assembled retrieval path and its freshness behavior.
How agent use changes the retrieval requirements and why precomputed indexes outperform agentic search on large monorepos
An agent without a precomputed index must discover where to look by traversing directories, searching strings, and opening files. On a large monorepo, that search can use up its context budget before useful work begins. Token price is not the main distinction. An existing index supplies focused context, while an unindexed architecture requires rediscovering the codebase for each task.
Claude Code’s default agentic approach uses directory traversal and grep, avoiding the staleness risk of a maintained embedding index. Anthropic acknowledges the corresponding tradeoff. This works best when the agent already has enough context to know where to look, while vague relationships across enormous codebases can exhaust context. Precomputed retrieval is therefore most valuable where repository breadth makes unguided exploration expensive.
MCP connects that retrieval layer to Claude Code, Cursor, Codex, Windsurf, and other compatible agents. It separates agent choice from index choice. The index discovers relevant code, the agent reasons over it, and MCP delivers access between them. Repository intelligence can extend the same model beyond code structure to git history, hotspots, co-change patterns, ownership, and change risk, giving the agent context about a proposed change.
How deployment model and data privacy constraints interact with indexing architecture choices
For ITAR, CUI, or air-gapped environments, deployment constraints can eliminate an otherwise attractive tool before latency is considered. Code location is a hard boundary. Cloud-hosted semantic indexing that sends source to an external embedding service is incompatible with a requirement that source remain inside the perimeter. Preserving semantic retrieval under that constraint requires self-hosted indexing and an embedding model that runs within the permitted environment.
Zoekt and OpenGrok provide self-hosted paths for lexical search and source navigation. Teams can also run Glean under their own control, though it needs substantial infrastructure, while CocoIndex lets them choose their own embedding model and vector database. With these choices, the team that runs the system takes on the responsibility. A self-hosted query service alone does not settle residency if its embedding provider still receives code externally.
Training restrictions are a separate contractual question. A service’s promise not to store code does not, by itself, prohibit using that code to improve models. Residency governs where processing happens, while the training clause governs permitted use. Teams need to check both constraints when they evaluate the architecture, before using a hosted performance result to guide a purchase.
How to read a monorepo indexing benchmark without being misled by it
Procurement requires architectural context for a benchmark whose result may reflect the dataset and query type that work best with the engine being tested. First, identify which tier it measures and whether that tier answers the team’s actual questions. Fast trigram retrieval does not establish intent-based recall, just as a semantic result does not establish exact-match performance.
Repository shape is the next source of mismatch. Tens of thousands of files do not represent millions of files across dozens of languages. Latency results also need their ingestion conditions, because a static snapshot hides the lag between a commit and a searchable result. The comparison also needs to cover where the tool runs and whether matching the reported performance takes hosted infrastructure, a self-hosted service, or a Kubernetes cluster that the team can reproduce.
First, establish whether exact and regex, symbol and structural, or intent-based queries dominate the workload. Second, establish deployment and data-residency constraints, eliminating incompatible options before comparing speed. Third, test freshness against the actual commit cadence and ask how failed or delayed embedding jobs are signaled. Fourth, where agents are involved, measure time-to-answer and token cost per task with and without a precomputed index.